
Comparing Foundational with Monte Carlo? Foundational defines data quality as contracts in your source code, so every team can review, version and scale its own rules. Data contracts defined in code, versioned and code-reviewed in Git, in an open format with no lock-in. Breaking changes caught before merge, with violations flagged in code review, not after the data lands. A complete data & AI governance platform with end-to-end coverage from Go, Python, Java and COBOL through BI, not just SQL or Spark.

Data contracts in your code
Reviewed, versioned, open format.
Production data observability
Monitors, anomaly detection and incident response.
Choose Foundational to catch breaking code changes at review time.
Choose Monte Carlo to monitor production data, detect anomalies, and manage incidents after data lands.
Foundational governs data quality in code, and Monte Carlo governs it in its platform.
 Foundational | Monte Carlo | |
|---|---|---|
| How rules are defined | YAML data contracts next to your code | Monitors set up in the UI, optional monitors as code |
| Where rules live | In each team's repo, reviewed like any code | In the platform, unless exported to code |
| Scaling across teams | Each team owns contracts in its own repos | Monitors managed in one platform, grouped by domain |
| Open format and portability | Open-format YAML, no lock-in, found by scanning your repos | Monitors as code need Monte Carlo's CLI and platform |
| When issues are caught | Violations flagged in the PR, before merge, and in production | Anomalies in production data, plus optional PR risk review |
| End-to-end coverage | Lineage from application and operational code through BI | Connected warehouses, pipelines and BI tools only |
Foundational makes data quality part of how your teams already ship code.
One source of truth, versioned and code-reviewed in Git.
Every team defines and owns its contracts in its own repositories.
Plain YAML you own, so moving away is easy.
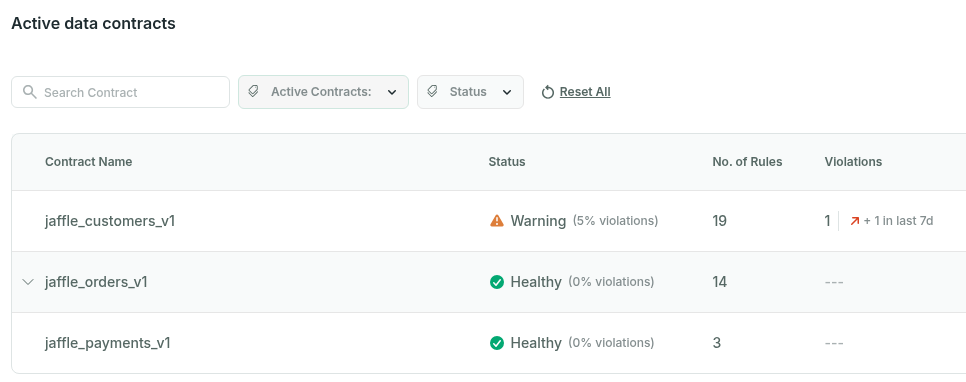
Foundational connects your application code and the tools your teams already use, from repositories to dashboards, across its supported languages and platforms, in one data & AI governance platform.
GitHub, GitLab, Bitbucket, Azure DevOps and more.
TypeScript, Go, COBOL, Scala, Java, Python, SQL, Spark, dbt, Airflow and many more.
Snowflake, BigQuery, Redshift, Databricks, PostgreSQL, Oracle and more.
Looker, Tableau, Power BI, Sigma, Metabase and more.
Foundational keeps data quality rules in your code, and Monte Carlo keeps monitors in its platform.

It depends on what you need most.
Foundational works next to observability tools, so each product keeps its own workflow. You can keep Monte Carlo for production anomaly detection and incident response, and add Foundational contracts so quality rules live in your code and breaking changes are caught before merge.
Foundational is an alternative when you want data quality defined as contracts in your source code, reviewed and versioned in Git, in an open format.
It's a complete data & AI governance platform, with always-up-to-date lineage from code, impact analysis, ontology, catalog and data quality, so AI and coding agents get accurate context.
Foundational data contracts are YAML files that live in your repositories, next to the code that produces the data. Every rule is reviewed, versioned and owned by the team that wrote it, and violations show up in code review before merge.
Monte Carlo monitors are set up in its platform, with optional monitors as code that use its CLI. Foundational contracts are open-format YAML that every team keeps in its own repositories, so they scale across teams and are easy to move away from.
Yes, if you want data quality rules defined in code, with review and versioning, that scale across many teams in an open format. It also catches breaking changes before merge and gives you lineage, ontology and catalog in one platform.
Foundational also checks your data in production against your contracts. If your priority is anomaly detection for issues you never wrote a rule for, Monte Carlo is built for that.
Yes. Foundational can work next to Monte Carlo, with contracts and pull-request checks in your code while Monte Carlo handles production anomaly detection and incident response.
Each product keeps its own workflow.
It analyzes application and operational code in TypeScript, Go, COBOL, Scala, Java, Python, SQL and many more languages, and connects to GitHub, GitLab, Bitbucket and Azure DevOps. It works with pipeline tools such as dbt, Spark, Airflow and Fivetran.
For warehouses and BI, it works with Snowflake, BigQuery, Redshift, Databricks, Looker, Tableau and Power BI, among others on the supported languages and platforms list.
Explore how proactive governance creates measurable impact across your entire data lifecycle.


